Script runner permanently bricked under sustained MIDI load

Hello! My goal is to have Ableset ping a couple Mio on stage every two seconds to monitor their health and provide latency information in my Canvas. I’ve gotten it working conceptually but when I flood the network with messages, the MIDI Mapping script on a busy input eventually kills the whole script runner and nothing scripted works again until AbleSet is relaunched.

To further explain, a MIDI Mapping script sits on an RTP input carrying about 24 messages/second of ordinary show automation. After roughly 40 minutes:

RangeError: Maximum call stack size exceeded
    at emscripten-module.1e0c139d.wasm:wasm-function[866]:0x479da
    at emscripten-module.1e0c139d.wasm:wasm-function[602]:0x2bb3e
    ...
scriptName: "Network TO VFX / Ctrl Ping"

From that moment, every attempt to create a script context fails:

RuntimeError: null function
    at emscripten-module.1e0c139d.wasm:wasm-function[694]:0x353ef
    at t._QTS_NewContext [as QTS_NewContext] (672.js:1:8673)
    at R.newContext (226.js:5:2785)
    at U.newContext (226.js:6:1257)
    at script-runner-44735674ee233813.js:1:11350

36,724 times over the next 25 minutes. No MIDI Mapping script runs, the Project Script stops, and its setIntervaltimers never fire again. Quitting and relaunching AbleSet is the only way back to normal operation.

Here are the rates I’ve logged

window MIDI in VMs created script errors
before the load increase 3.0 3.0 0
after, up to the crash 26.0 26.0 0
after the crash 23.6 0 23.6

VM creation tracks inbound MIDI exactly 1:1. It looks like a fresh QuickJS context is created for every message arriving on an input that has a script mapping, before the script can decide whether it cares. My script’s first line is a channel check that rejects the other 99% of traffic, but the context has already been built by then.

Crash came at t=5524 s into a 7029 s session, so about 92 minutes in, or roughly 85,000 contexts.

The Project Script publishes each machine’s transport state to the other so a canvas on either one shows both, and it drives a MIDI path monitor that pings our three MIO boxes and watches the round trip. When the runtime dies, that monitor silently freezes — the last values just sit there looking healthy.

My questions for you are

Is a QuickJS context per incoming MIDI message intended? A channel or CC pre-filter on script mappings would avoid the majority of them, and would be useful regardless of this bug.

Is there any way for a script to recover the runtime? My watchdog was a setInterval in the Project Script, which of course dies with everything else.

Anything I can do on my end short of removing the script mappings?

Will send logs to the support inbox as well - thank you for your help, really appreciate you!
Got it to crash again so following up with more info that I hope is helpful!

The Project Script’s long-lived context stops existing, while short-lived per-message contexts carry on working fine. On the second crash, I got No RangeError, no null function, nothing in the log. The script writes /shared/A_hb, /shared/A_cpu, its ping values, and then is never heard from again. Meanwhile 853 per-message contexts ran successfully afterward.

The onOscChange callbacks died at the same instant as the setInterval timers — the last /shared/A_pos write from my beatsPosition listener is in the same 1.5 s window as the last timer tick. So it’s the whole context going away rather than timers being descheduled.Both deaths came after roughly ten minutes at ~50 MIDI messages/second arriving on inputs that have script mappings. Since a QuickJS context is created per message, that’s 50 contexts created and destroyed per second, sustained. Early in each session the rate was ~1.5/s and nothing went wrong.So maybe something reclaims or evicts the long-lived context under sustained churn from the short-lived ones. I can’t see inside the runner so that’s inference from correlation — but it’s tight across both sessions, and the asymmetry seems like the diagnostic part: short-lived contexts keep working, the long-lived one doesn’t.

Is there a context limit or eviction policy in the script runner that the Project Script’s context can fall foul of?

When it goes silently, is there anywhere else that gets logged?

Is there an OSC command to reload the Project Script? That would at least let me build my own recovery, since a setInterval watchdog dies with the thing it’s watching.

Putting the second crash log in your support inbox as well, hopefully this is helpful info rather than just confusing. Thought I had the reason for the crash the first time but seems like I was wrong!

Hey @hank, thank you for reporting this issue. I’ll look into it soon!

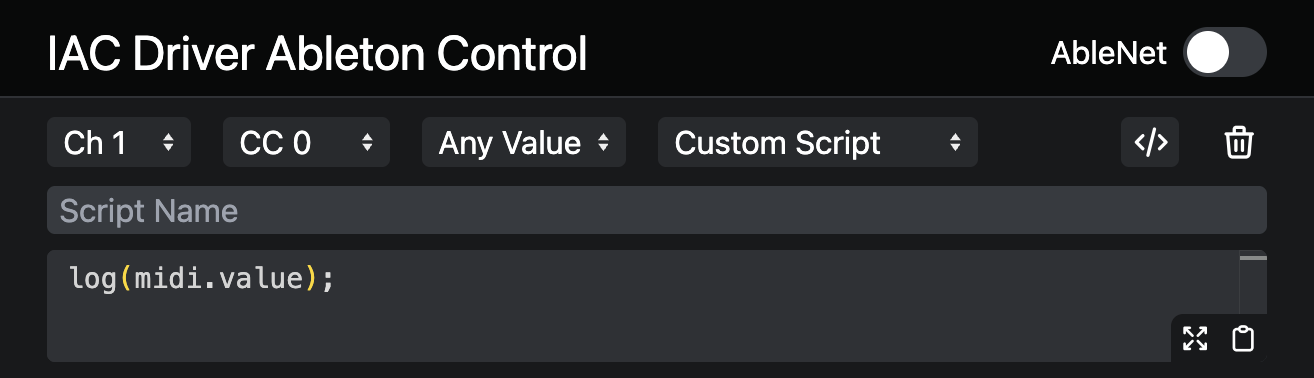
In the meantime, you can scope the script to a specific MIDI event by adding a CC mapping and select Custom Script as the action:

Would that work for you?

That will certainly work, thank you so much! I didn’t realize Custom Script was available as an action on a scoped mapping so my receivers were bare script rows. Every message on a busy input was spinning up a context so scoping them like this should take it down significantly.

Maybe worth keeping the underlying issue open when you get time to check it out. The Project Script’s context going away silently while per-message contexts carry on is still the part that worries me. I was really only able to crash it by flooding it and the scope avoid that for me so not a high priority fix but maybe when you get time, I’d love your thoughts. Thanks again Leo!!

Hey @hank, I’m glad I could help!

I just released a new beta version that addresses this issue and should be more stable when a script is called rapidly thousands of times :slight_smile: